How I'd Bring Discipline to AI-Assisted Coding at Team Scale
I've been vibe coding solo for over a year — fast, no process overhead, just me and the tools. Then people kept asking: how does that discipline survive once it's a team, not just you? Turns out I'd already built an answer for workfOS, without knowing there was a name for it: Spec-Driven Development. A friend at Fannie Mae mentioned a tool called OpenSpec, and comparing notes was humbling in the right way. Wrote up what my homegrown process gets right, what the tooling gets right, and where they need to meet.
I’ve been vibe coding for over a year now. I love it. Cursor and Claude Code have changed how fast I move — entire subsystems get built in a sitting, and I spend my time thinking about architecture instead of typing boilerplate.
But every project I’ve built this way has been solo. It’s just me, alone with the tools, making every call myself.
That’s a meaningfully different problem than the one people keep asking me about. As someone who’s spent three decades doing enterprise architecture — federal, financial services, systems where dozens of engineers touch the same codebase — I get asked some version of the same question a lot: how do you bring AI-assisted coding to a team? What discipline does it need once it’s not just you?
The Session Briefs Approach: Origins and Rationale
My working answer, so far, is something I didn’t set out to design. It emerged from actually building something.
For the past several months I’ve been building workfOS — an agentic AI platform that deploys specialized AI “workers” for non-technical business owners. It’s still just me writing the code, but I split the work with Claude and Cursor in a way that, in hindsight, looks a lot like a discipline of its own. I call it Session Briefs.
Here’s how it works. I break the work into sessions — each one a chunk small enough to reason about completely, but large enough to represent a real unit of progress. For each session, I go back and forth with Claude, not writing code, but nailing down exactly what the session should include: the scope, the architectural decisions, a rough plan, and the list of tasks needed to get there. This is deliberate, slow, sometimes tedious work — and it’s where most of the actual thinking happens.
Once that brief feels solid, I hand it to Cursor and ask it to hold the brief up against the real codebase. Cursor comes back with gaps — places where the brief assumed something that isn’t true anymore, missed a naming convention, or overlooked a dependency that already exists. I take those gaps back to Claude, we resolve them, and the brief gets sharper. This loop runs two or three times before I call the brief implementation-ready.
Only then does Cursor get to plan the actual work — breaking the brief into concrete tasks — and start writing code.
No architecture gets decided during implementation. By the time Cursor is generating a task plan, every meaningful decision has already been made, argued over, and locked. Cursor’s job at that point is execution, not judgment.
I didn’t build this because I’d read about spec-driven development. I built it because, without it, I could feel the same failure mode creeping in that I’d seen for years on large human teams — different people (or in my case, different tools) quietly drifting apart on what the system was actually supposed to do. The brief was my way of making that shared understanding explicit before code could paper over the disagreement.
Spec-Driven Development (SDD)
A few days back, I was talking to an old friend, a director at Fannie Mae, and he asked if I’d heard of OpenSpec. I hadn’t. I told him about vibe coding, and about how multiple people had separately asked me the same question: how do you scale AI-assisted coding to enterprise projects, where a large number of developers have to work on the same codebase? His question sent me looking into what OpenSpec actually was — and from there into the broader category it belongs to.
The core idea of Spec-Driven Development, or SDD, is simple to state and hard to argue with: make the spec the source of truth, and treat code as a derived, regenerable artifact. Not documentation that trails behind the code and quietly goes stale — a version-controlled spec that the code is generated from, and that gets updated first when things change. Some of this is expressed through notation like EARS (Easy Approach to Requirements Syntax), which turns a fuzzy requirement into something testable and machine-parseable — “WHEN the user submits an invalid form, THE SYSTEM SHALL reject it with a specific error” — in roughly the spirit of Gherkin and BDD, but built for an AI agent to read and act on rather than a human tester.
The most concrete implementation of this I found is OpenSpec, and it’s worth describing because it maps onto my own process more closely than I expected. OpenSpec keeps two directories: specs/, which holds the current, agreed state of the system, and changes/, which holds active proposals — deltas against that current state, not yet merged in. The workflow is propose, apply, archive: you write a delta, it gets validated strictly before any code is touched, it gets implemented, and then it’s folded back into specs/ as the new baseline. There’s also a newer feature called Stores, aimed at team scale specifically — a platform team can own a set of specs in a shared repo that product teams reference read-only, which is basically the shared-services pattern I spent years living inside at GSA, just applied to specs instead of APIs.
There’s a handful of other tools playing in the same space — GitHub’s Spec Kit, AWS Kiro, BMAD, Tessl, Google’s Antigravity, cc-sdd — and they mostly split along one axis: some assume a static, greenfield spec you write once and build from, others assume an iterative, brownfield world where the spec keeps evolving alongside a live system. OpenSpec’s delta model puts it firmly in the second camp, which is why it’s the one that resembles enterprise reality — and my own reality with workfOS — more than the others.
Comparing Notes with Spec-Driven Development
I went in expecting to find that I’d built a weaker, ad hoc version of this. What I actually found was more interesting: I’d built the same shape without knowing the name for it.
PROJECT_SPEC.md, the living document I keep for workfOS, is functionally my specs/ — a single file instead of a directory tree, but genuinely current, updated after every session with a status table of what’s built and where it lives. Each CURSOR_BRIEF_SESSION*.md is functionally a delta in changes/ — a proposed unit of work, not yet merged into the baseline. My rule that no architecture gets decided during implementation is, word for word, OpenSpec’s strict validation gate before code is touched. I didn’t converge on this by studying SDD. I converged on it because the problem — different minds, or different tools, quietly drifting apart on what the system is supposed to do — is the same problem, and there are only so many honest ways to solve it.
But finding the same shape isn’t the same as finding the same rigor, and once I looked closely, the gaps ran in both directions.
OpenSpec is more disciplined than I am in a few specific ways. The archive step — folding a delta back into the baseline — is a forced, discrete action in their workflow. Mine is a manual one: I update PROJECT_SPEC.md by hand after a session, and nothing enforces that I actually do it before starting the next one. It’s held together by my own discipline, not by the tool. OpenSpec also gives requirements a testable shape through EARS; my briefs lock architectural decisions in prose — precise prose, but not something a tool could mechanically check against the running system without an agent re-reading and re-reasoning about it every time. And OpenSpec organizes its deltas by capability, so anyone can ask “show me everything ever decided about the training pipeline” and get a clean answer. My deltas are organized by session number — great for reading history in order, much worse for finding everything related to one subsystem after the fact.
But my process is more disciplined than OpenSpec in ways that matter just as much, and that I don’t think the SDD tooling world has fully reckoned with yet.
OpenSpec’s validation is fundamentally a check against the spec itself — is the delta internally consistent, does it conflict with another proposal. My validation is a check against the actual, running codebase. When I handed Cursor the Session 21 brief for workfOS, it came back and told me the brief had the worker numbering wrong — it called the Communications Manager “Worker 3” when Worker 3 was already the Recruiter, built and shipped two sessions earlier. That’s not a spec-consistency error. That’s a codebase-reality error, and no amount of schema validation catches it — you need something that has actually read the code as it exists today. Cursor did.
I also have something OpenSpec doesn’t formalize at all: a feedback loop for when implementation drifts from spec anyway. My process explicitly closes that loop — I validate what Cursor built independently, and if it diverged from the brief, that divergence gets reported back and shapes how I write the next brief. SDD tooling generally assumes that once a spec is validated, it’s followed faithfully. In my experience, agents still improvise under ambiguity during implementation, spec or no spec, and if you don’t have a mechanism to notice and correct for that, you’re trusting a process to be perfect that was built by fallible tools.
And then there’s the part of my process that isn’t really requirements at all. Decisions like “model selection is a platform choice, never customer-facing” aren’t observable system behavior you can express as WHEN/SHALL. They’re organizational stance — the kind of judgment call an architect makes, not a requirement a test can verify. EARS is very good at describing what a system does. It has nothing to say about why you’d choose one architecture over another when both satisfy the same testable requirements. My decision-locking pattern was built by an architect, for architectural judgment. SDD tooling, as far as I can tell, was built by engineers, for requirements decomposition. Different problems, and mine is the harder one to automate away.
Conclusion
So where does that leave me — two processes, built for different reasons, answering the same question with different amounts of rigor in different places.
That capability-versus-session-number gap is the one that should worry me most, because it’s the exact failure mode I set out to solve in the first place. Session Briefs work today because the “team” is really me, Claude, and Cursor: three interfaces onto one mind, where the missing rigor gets patched by the fact that I remember last week’s decisions. That stops being true the moment a second engineer joins without having sat through a single brief negotiation. They won’t have my memory. They’ll have PROJECT_SPEC.md, in whatever state I last remembered to leave it.
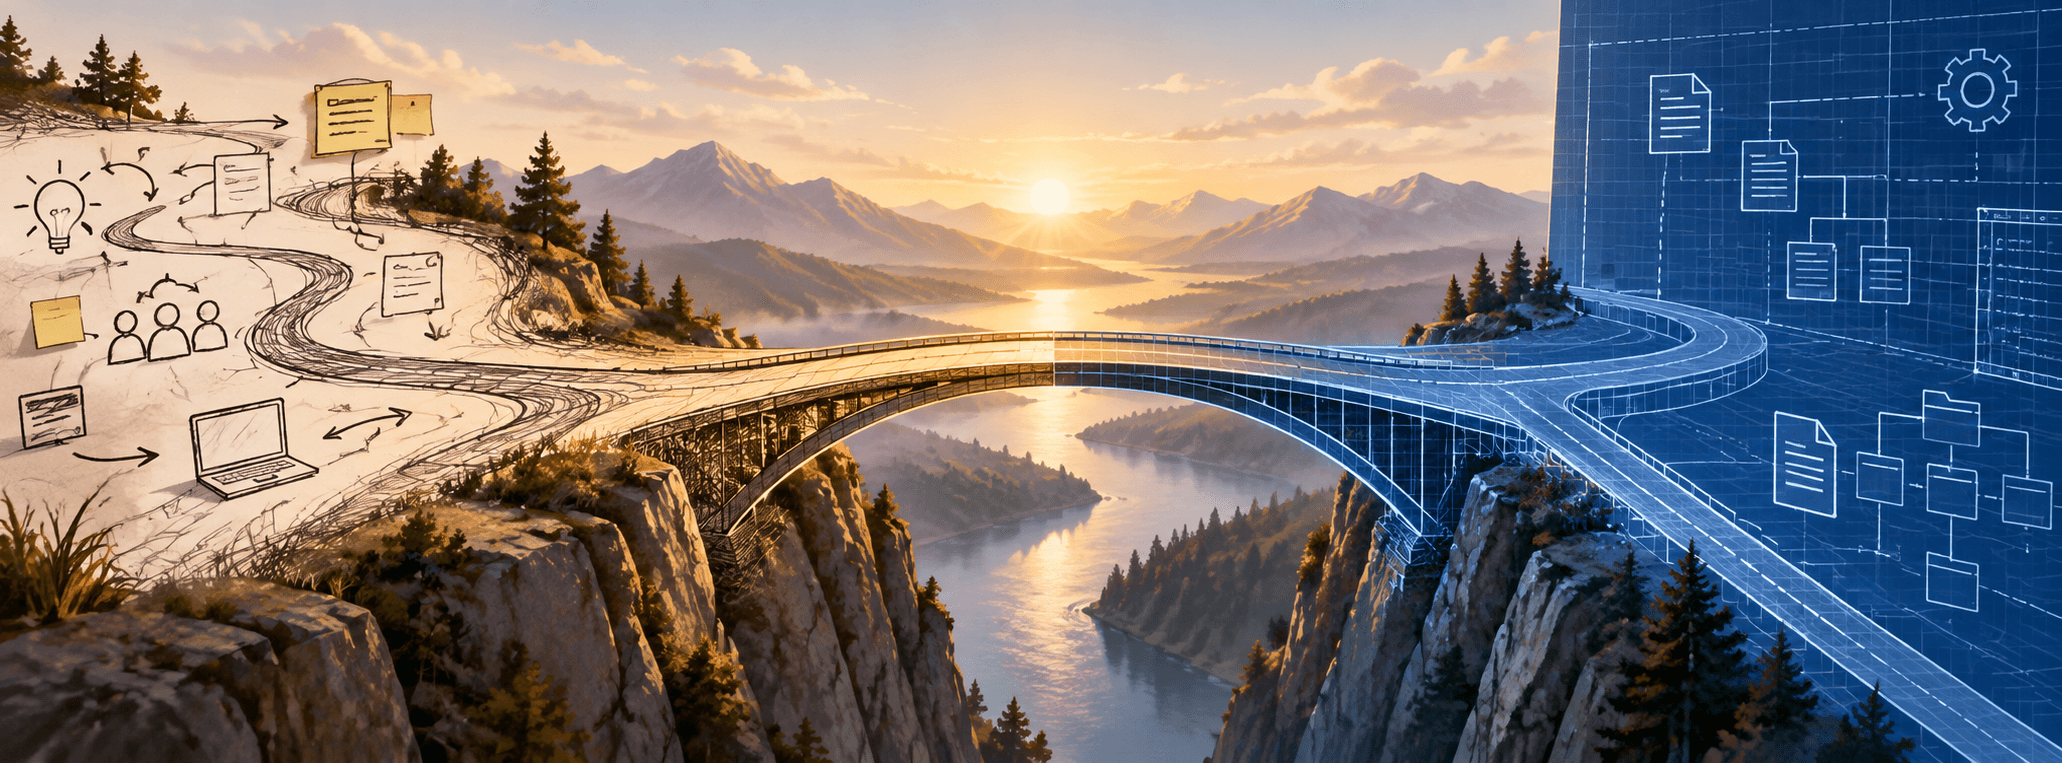
So the bridge isn’t choosing one process over the other — it’s grafting the parts of SDD that exist to survive a second contributor onto a process that already handles judgment and reality-checking better. Concretely, before workfOS actually needs it: make syncing PROJECT_SPEC.md a mandatory last step of every session, not a habit; write EARS-style acceptance criteria into each brief for the genuinely testable parts, so Cursor can check some of it mechanically instead of reasoning through the whole brief from scratch; and reorganize the spec by capability instead of session number, so it answers “what’s true about X right now” as easily as “what happened in order.”
None of that touches the part I’d be reluctant to give up — the decision-locking, the codebase-grounded validation, the deviation feedback loop. Those aren’t gaps. They’re why this has held up as long as it has, solo. SDD isn’t a replacement for that discipline — it’s the scaffolding that lets it survive contact with people who weren’t in the room when the decisions got made.
That’s my answer to the question I kept getting asked. You don’t bring discipline to AI-assisted coding at team scale by adopting someone else’s framework wholesale. You bring the discipline you already have, and add exactly the parts that were only working because you happened to be the only one who had to remember anything.
Comments (0)
Leave a Comment
Loading comments...
Post Details
Author

Anupam Chandra (AC)
Tech strategist, AI explorer, and digital transformation architect. Driven by curiosity, powered by learning, and lit up by the beauty of simple things done exceptionally well.
Published
September 23, 2026
Categories
Reading Time
10 min read